October 2026
A small model with a zeroshot loop matches a larger one at 58% of the cost.
On 20 ProgramBench tasks, GPT-5.6 Luna in a build-and-check loop reached GPT-5.6 Sol's single-shot score at a median 58% of Sol's cost. At the same cost as Sol, the loop scored higher on 15 of the 20 tasks. Asking one Luna session to do both jobs didn't produce the same result. All 100 of those sessions stopped after one build.
What the loop is for
In this study, we asked 100 Luna sessions to build a program and check their own work. All of them stopped after 4 to 20 minutes, with about half of the hidden tests passing. Each session had up to six hours available. We wanted to see whether a separate checker could find problems and keep the builder working.
A review loop gives building and checking to separate sessions. When the builder believes the task is done, a checker tries to break the result. If it finds problems, the builder gets the findings and tries again. Both use the same model and task statement, but the checker starts without the builder's transcript.
We tested this on ProgramBench. Each task gives an agent a compiled program and its documentation, offline, and asks it to reimplement the program from observed behaviour. Our 20 tasks include svgbob, xz, samtools and direnv, with 262 to 1,425 hidden tests per task. None of the published runs on these tasks passes every test. The best scores range from 38% to 99%.
What we ran
We ran a two-node graph in zeroshot, our open-source runner for graphs of coding agents. One builder turn is a build, one checker turn is a check, and the pair is a round. The builder keeps its session across rounds. Each check starts fresh with only the task statement and workspace. A rejection sends the checker's discrepancies back to the builder. The run ends when the checker accepts, after 50 rounds, or at six hours.
We wrote the two prompts below before the first run and kept them unchanged across tasks. The model also receives ProgramBench's task statement and the runner's standard builder or checker instructions.
builderComplete the task described in the input. Keep working and verifying your own work until you believe the result fully satisfies the task. If review feedback is provided, address every point without breaking what already works.
checkerIndependently judge whether the current workspace satisfies the task. Derive your own checks from the task statement and whatever it makes available; do not rely on the builder's tests, notes, or claims. Run the checks. Accept only with concrete evidence that nothing is wrong. Otherwise reject and list the most important discrepancies, each with a minimal reproduction.
Luna and Sol are the small and large models in the GPT-5.6 line. We ran both through OpenAI's Codex CLI at its xhigh reasoning-effort setting. At the prices used for this study, Luna cost $0.20 per million input tokens and $1.20 per million output tokens. Sol cost $4 and $20 respectively. Sol ran each task five times as a single shot, meaning one build with no checker. Luna's loop also ran five times per task.
1.The loop reaches Sol's score at 58% of Sol's cost
We compared the cost of reaching the same score. Luna costs about a twentieth of Sol per token, but a loop also pays for checks and repairs. For each task, we scored the loop's five runs build by build. At each budget, we took the last build each run could afford and averaged their scores. The cost to match is the smallest budget where that average reaches Sol's mean single-shot score, expressed as a share of Sol's cost on the same task.
We expected the loop to cost less on most tasks, especially when Luna's first build was already close to Sol's score. On tasks where the first build was far behind, 50 rounds might still not close the gap.
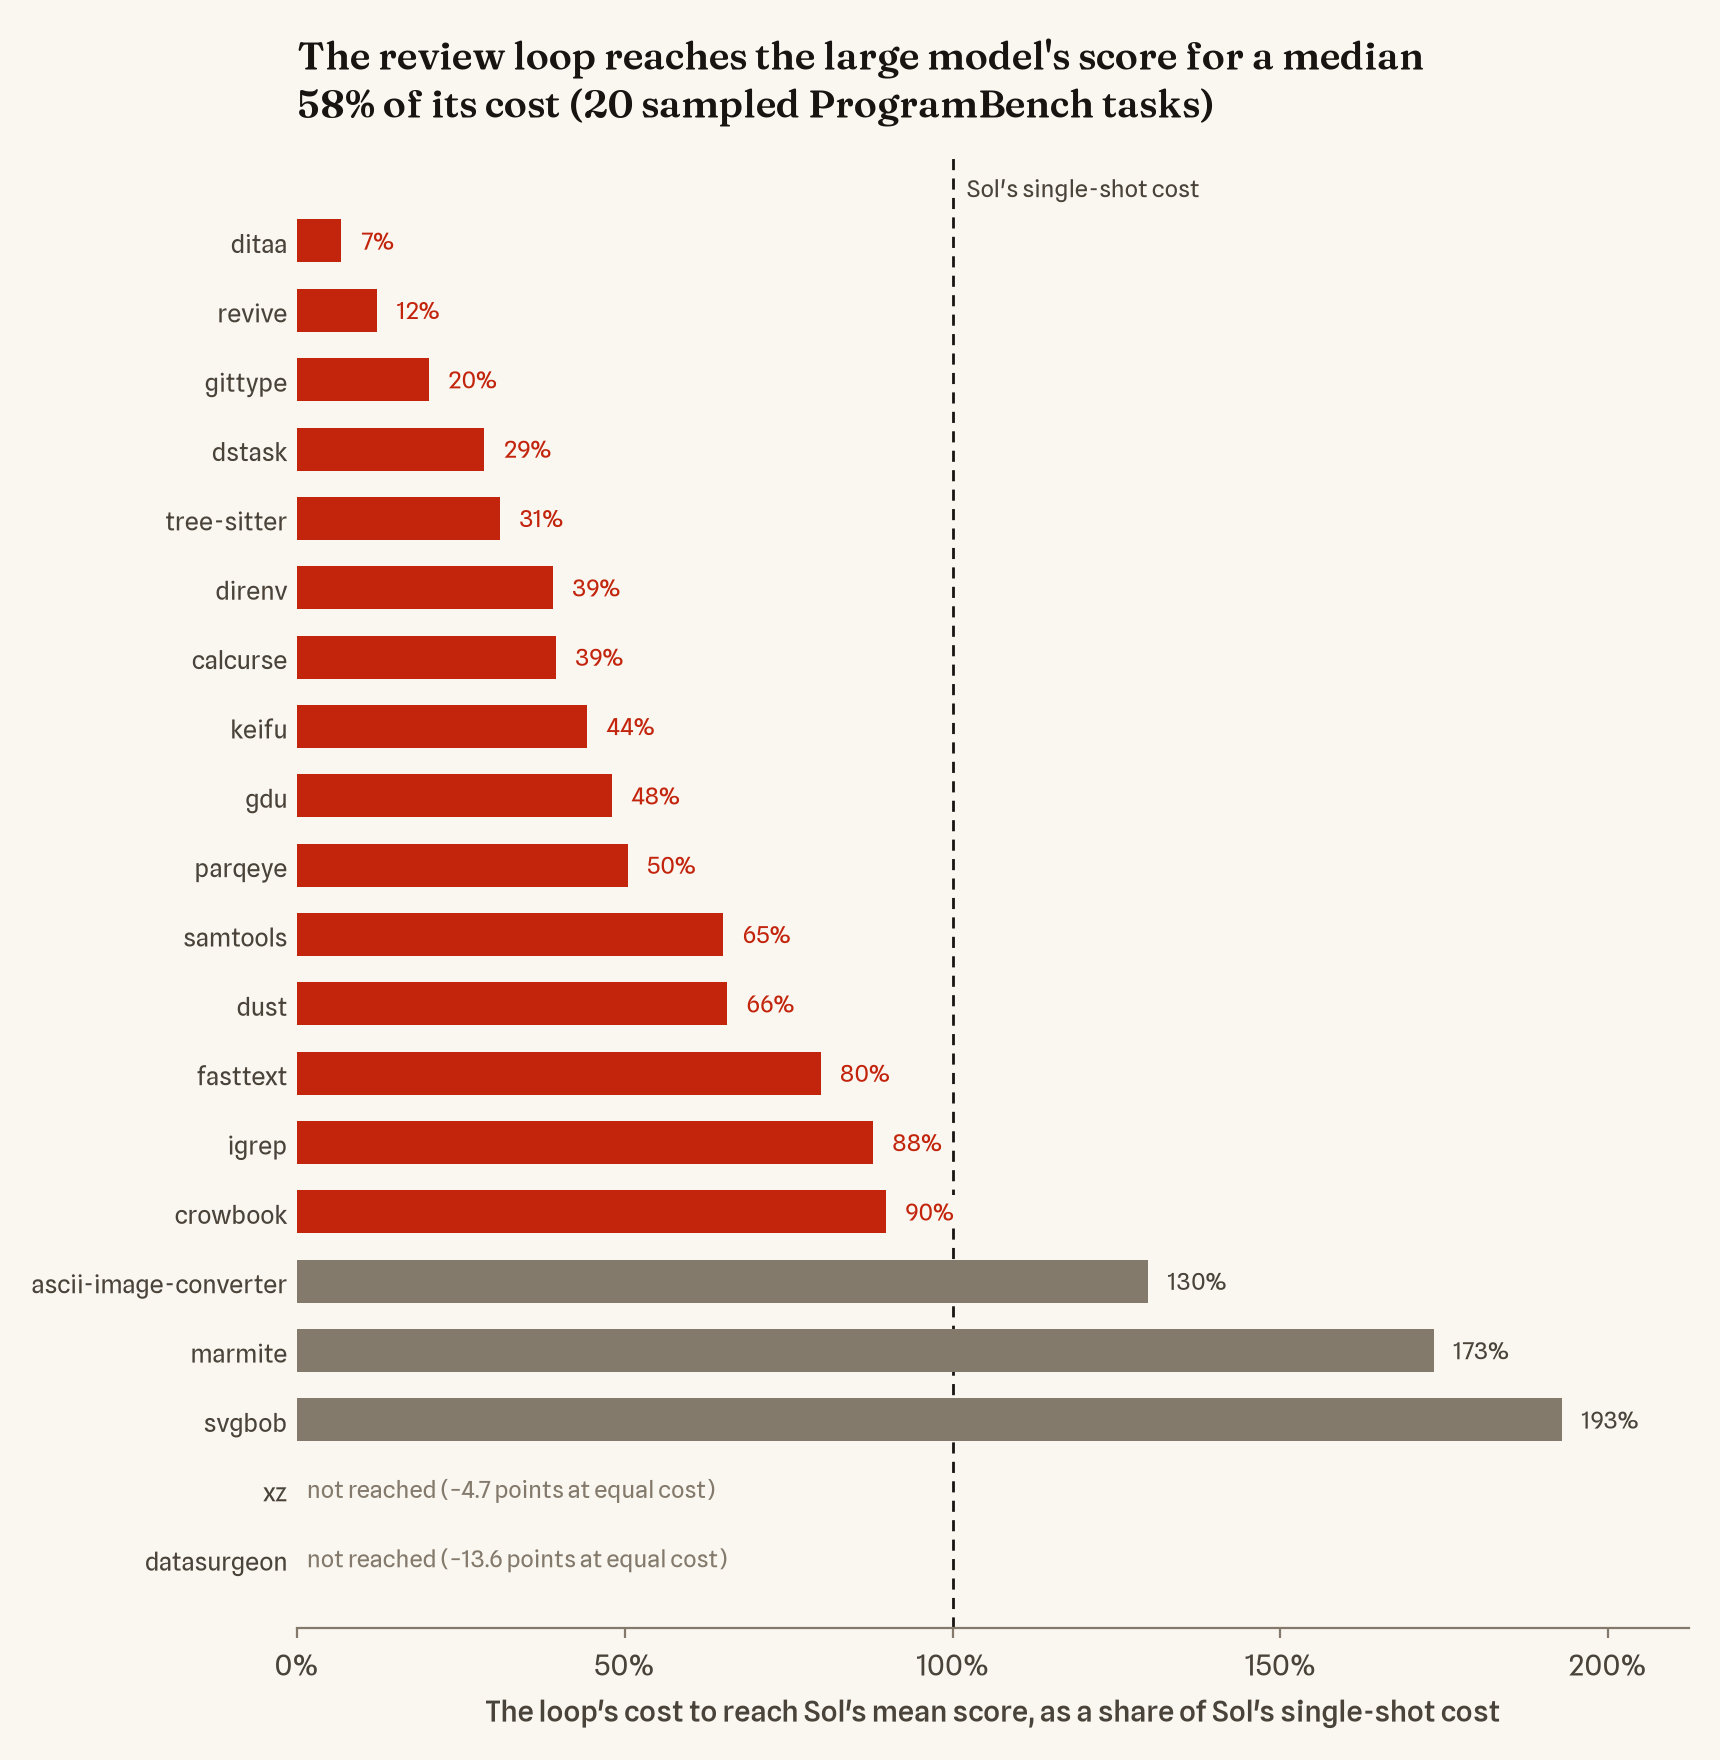
On 15 of the 20 tasks, the loop reached Sol's mean score for less than Sol's single-shot cost. Across all 20, the median was 58% of Sol's spend.1 Three tasks cost more, at 130% to 193% of Sol's spend. On the remaining two, datasurgeon and xz, the loop hadn't reached Sol's score by its last build.
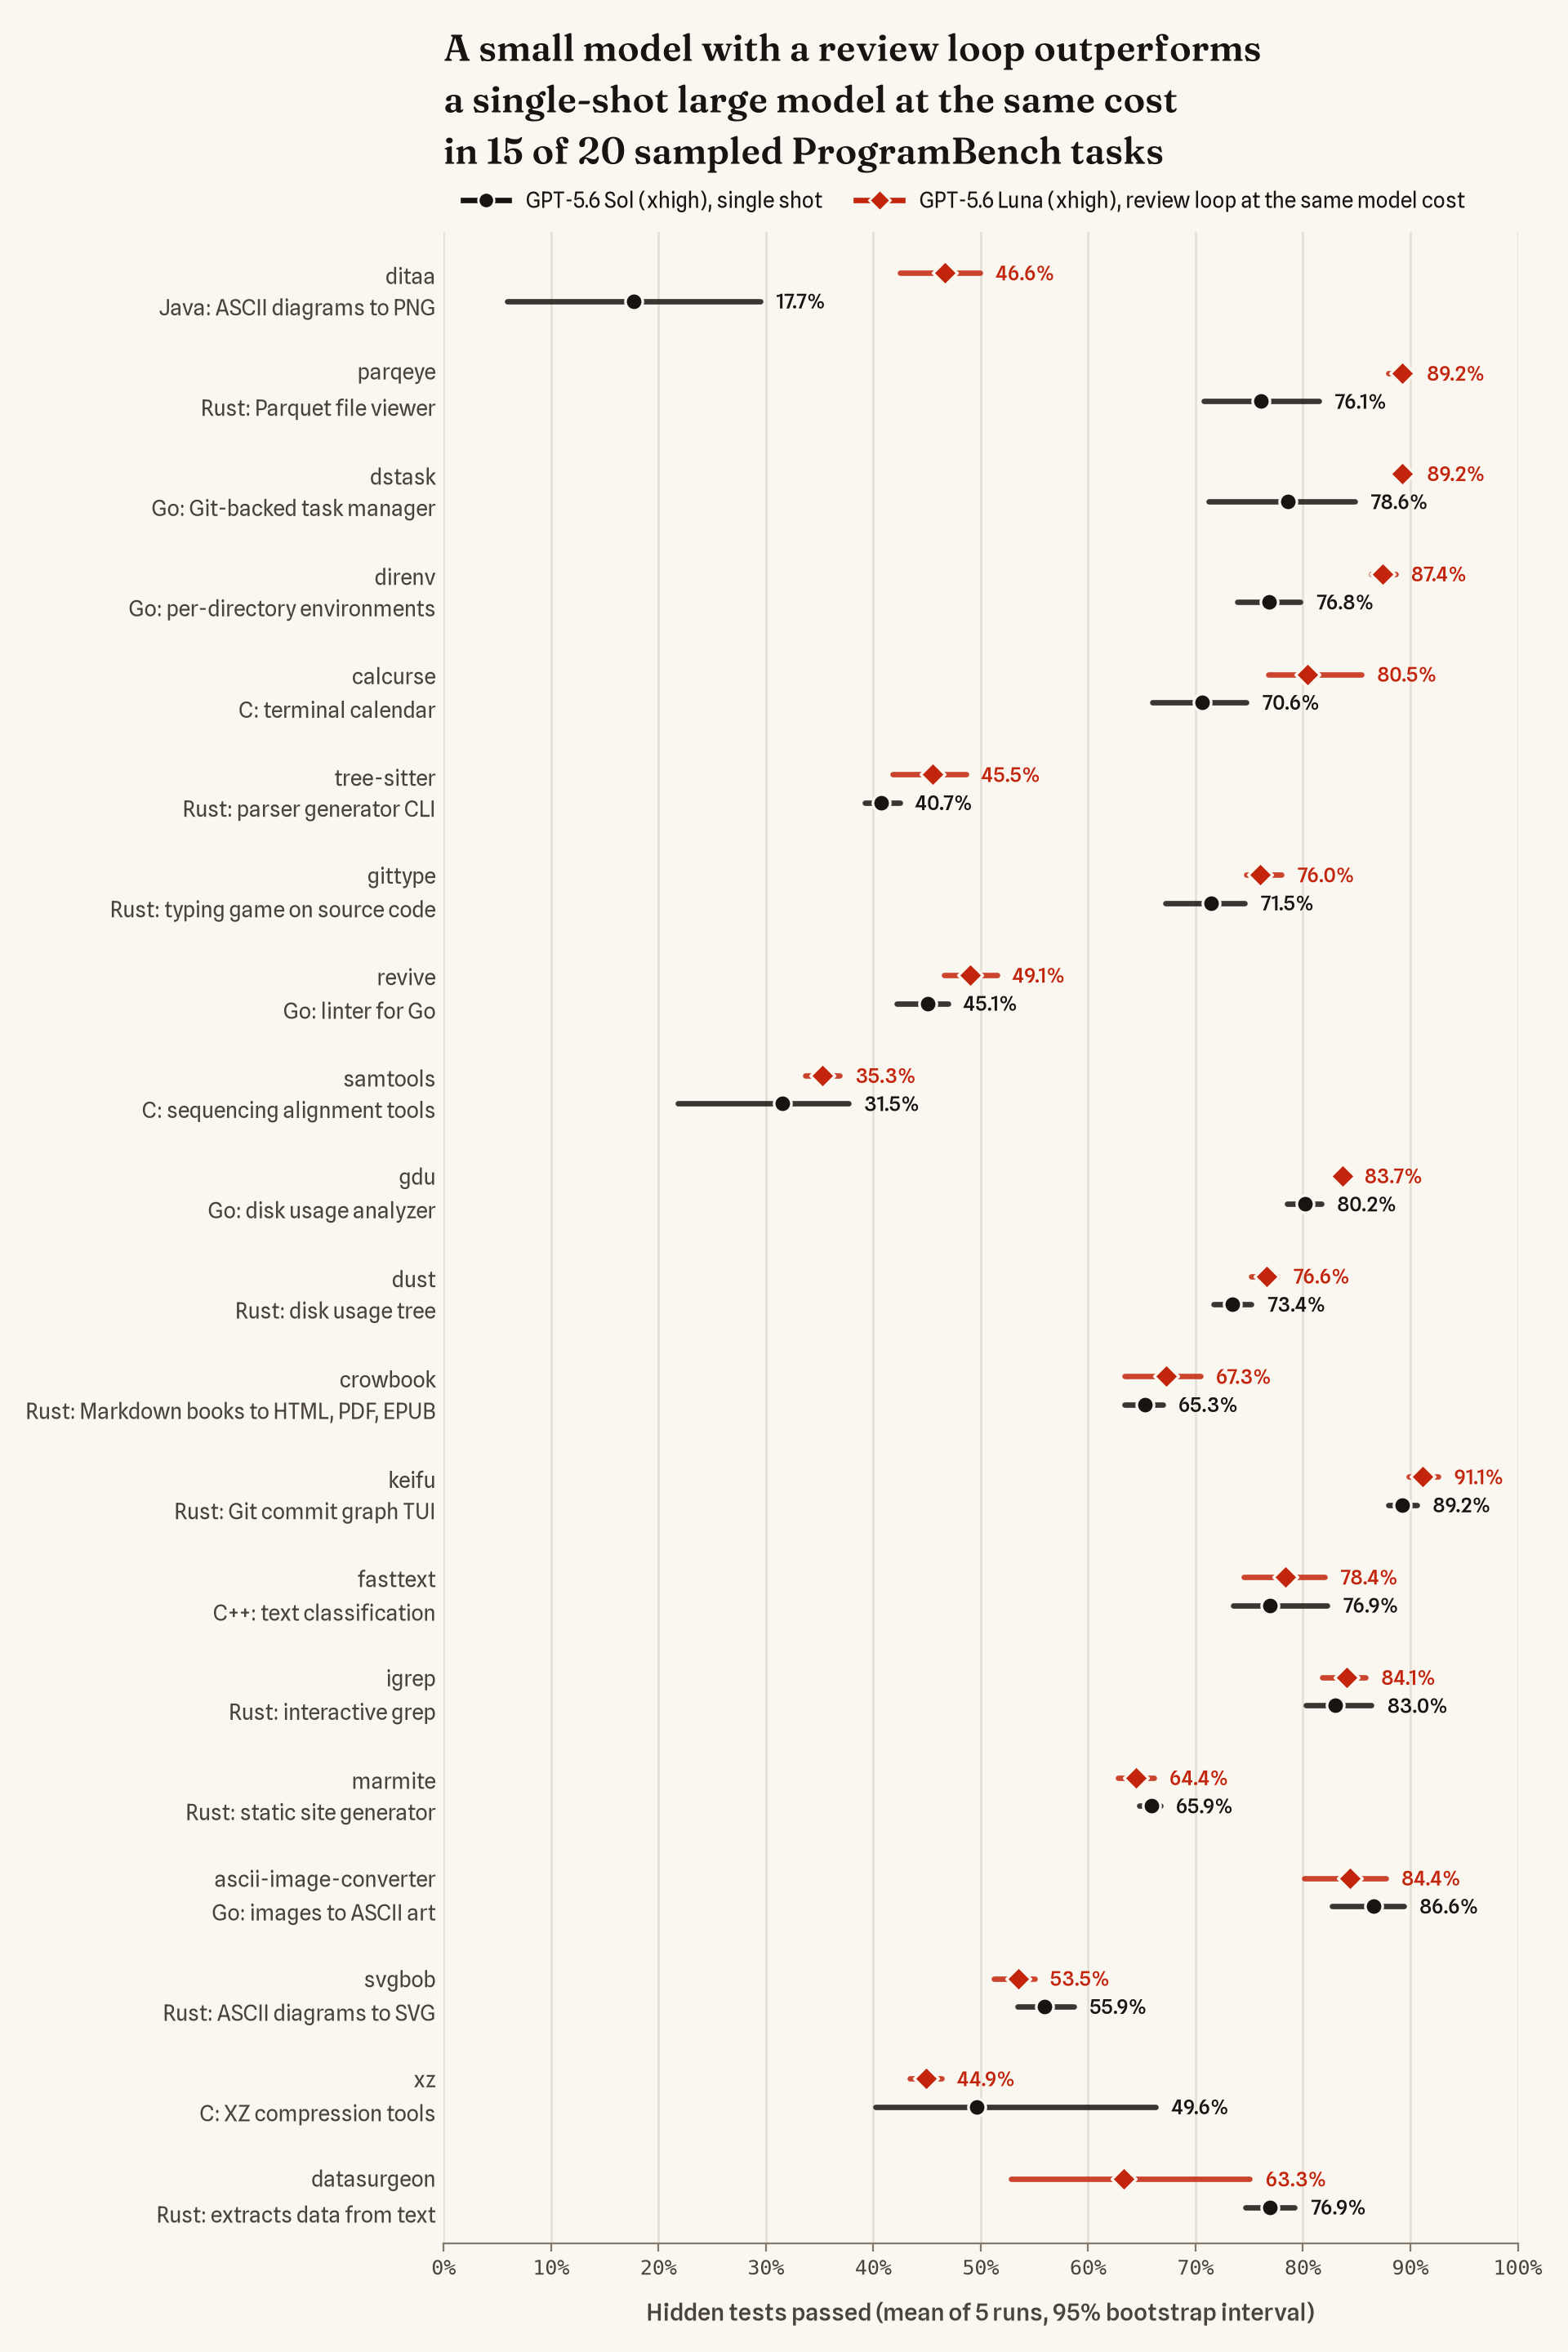
We also compared scores at the same cost. Taking each loop's last build within Sol's mean budget on the task, 11 to 50 rounds in, the loop scored higher on 15 of the 20 tasks.2 On seven of those tasks, ditaa, parqeye, dstask, direnv, calcurse, gittype and gdu, the 95% intervals of the two means don't overlap. They do overlap on all five tasks where Sol leads.3 Averaged over the tasks, the loop passed 69.5% of hidden tests, compared with Sol's 65.6%.
The loop took longer. It needed a median 69 minutes to reach Sol's score and 2.3 hours to spend Sol's budget, compared with 11 minutes for Sol's single shot. These are medians of the per-task averages.
2.A single session given both roles stops after one build
The checker's instructions might explain the improvement. If giving one session both prompts produced the same result, there would be little reason to run a separate checker.
We expected a session given both roles to stop early. The builder prompt already asks it to verify its work, so another instruction to check seemed unlikely to change when it stopped. The alternative was that it would keep working as long as the loop and reach a similar score.
We gave Luna the builder and checker prompts above, verbatim, along with the runner's standard checker instructions. We joined them with the four sentences below and called the combined instructions the role prompt.
glueWork in rounds. In each round, act first as the builder and then as the checker, following the instructions for each role below. If the checker rejects, its list of discrepancies is the review feedback for the builder in the next round. Repeat until the checker accepts, then return.
The model, task statement, six-hour limit and five runs per task were the same as in the loop. The only change was using one session instead of two.
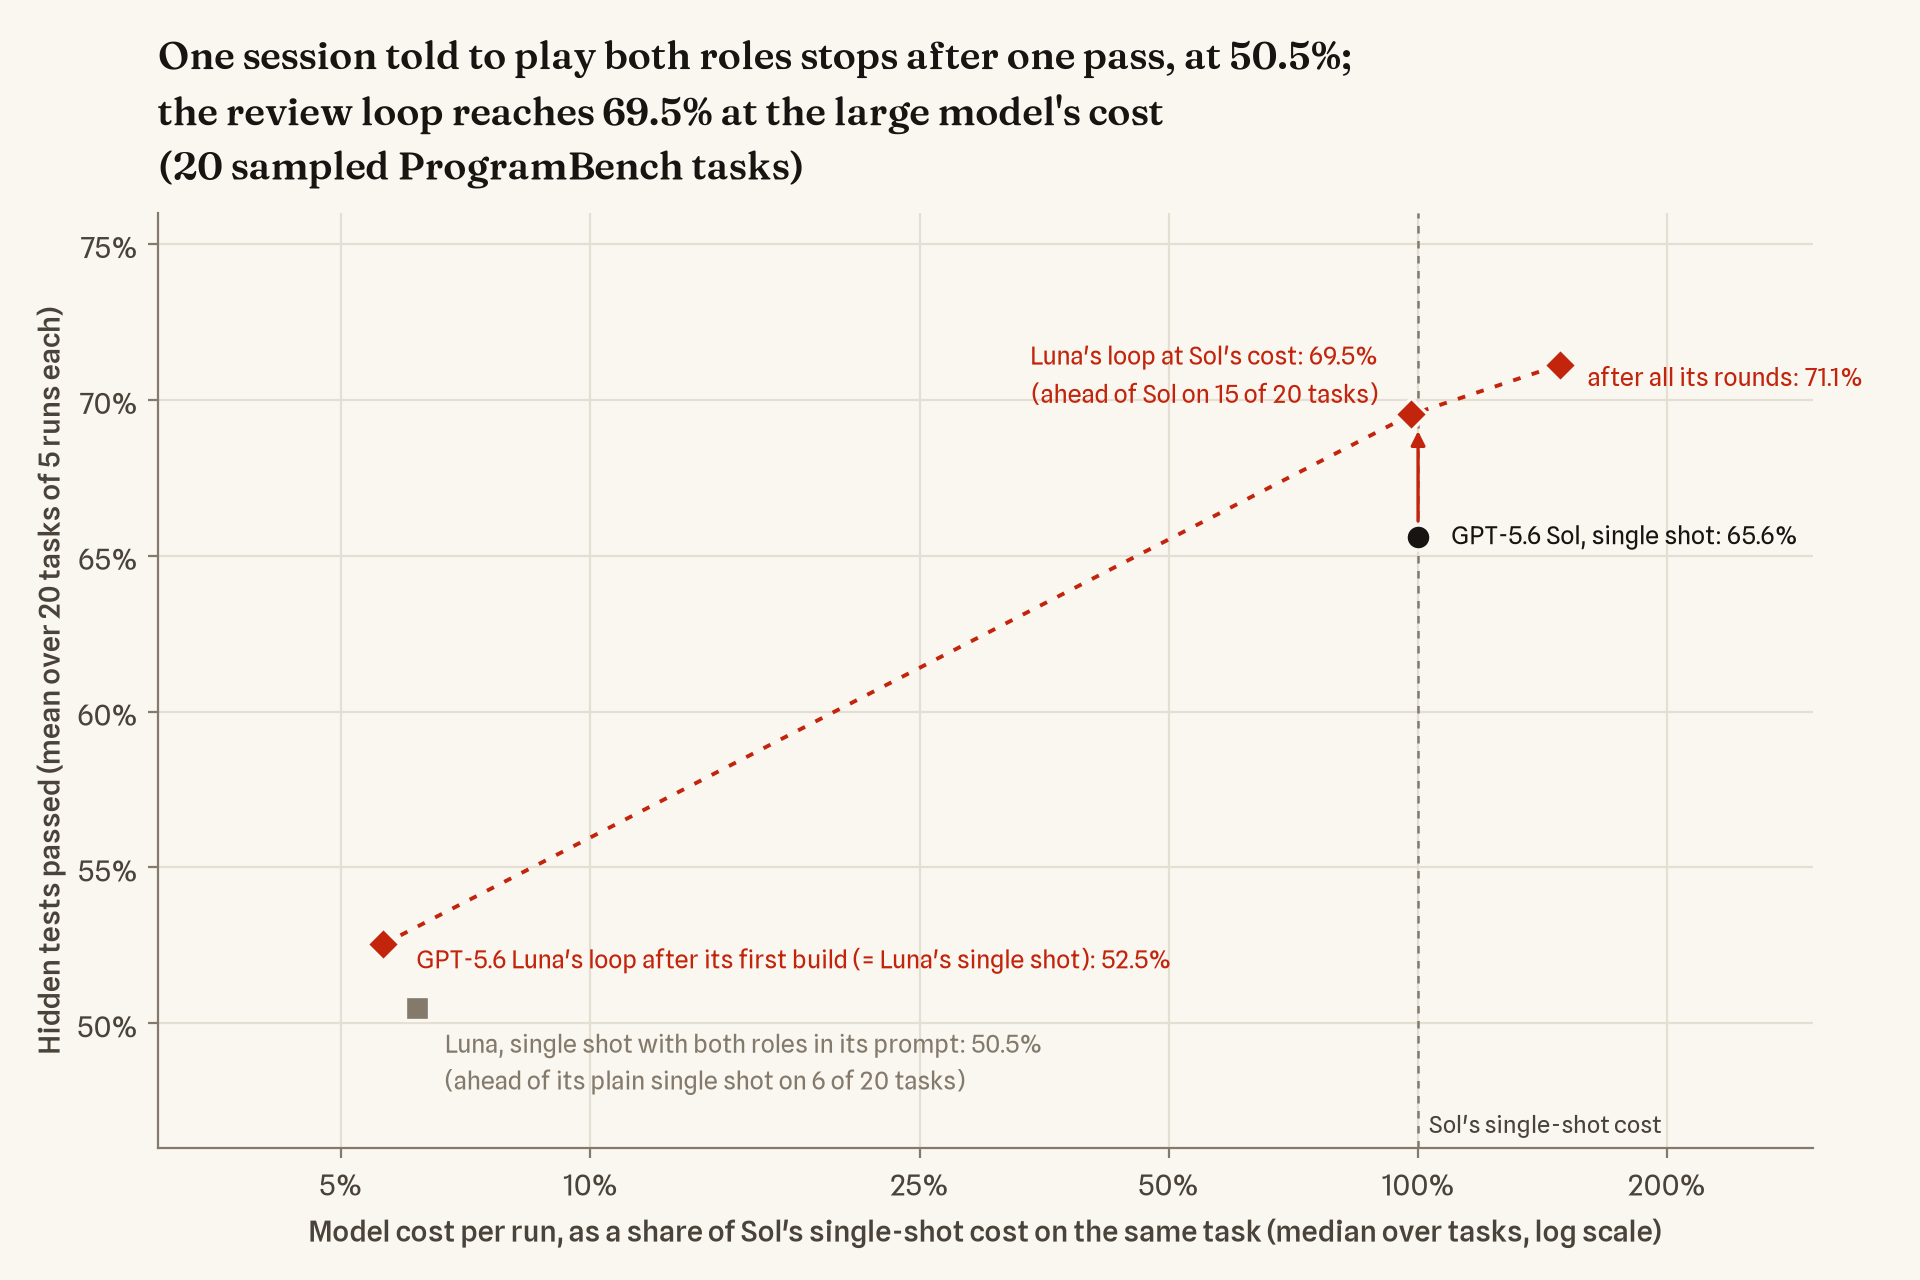
All 100 sessions stopped on their own after 4 to 20 minutes, with a median of 9 minutes, at about the cost of one build. Their average score was 50.5%, two points below Luna's plain single shot, which is the loop's first build. At that budget, the loop had also completed exactly one build in all but one of the included runs.4 The plain prompt scored higher on 14 tasks and the role prompt on six. The loop improved with further rounds, reaching 69.5% at Sol's budget and 71.1% after all its rounds.5
3.The loop is more reliable
An average score can hide badly failed runs. We checked how much scores varied across repeated attempts at the same task.
We expected the loop's scores to vary less than either model's single shots, and Sol's single shots to vary less than Luna's.
The figure below pools all 20 tasks. Each point is a run's score minus the mean for its setup on that task. We compared four setups, called arms in the figure. These were Sol's single shot, Luna's single shot, Luna with the role prompt, and the loop at Sol's budget. In the loop, 86% of runs landed within five points of their task's mean. The figures were 72% for Sol's single shots, 65% for Luna's single shots and 62% for the role-prompt sessions.6
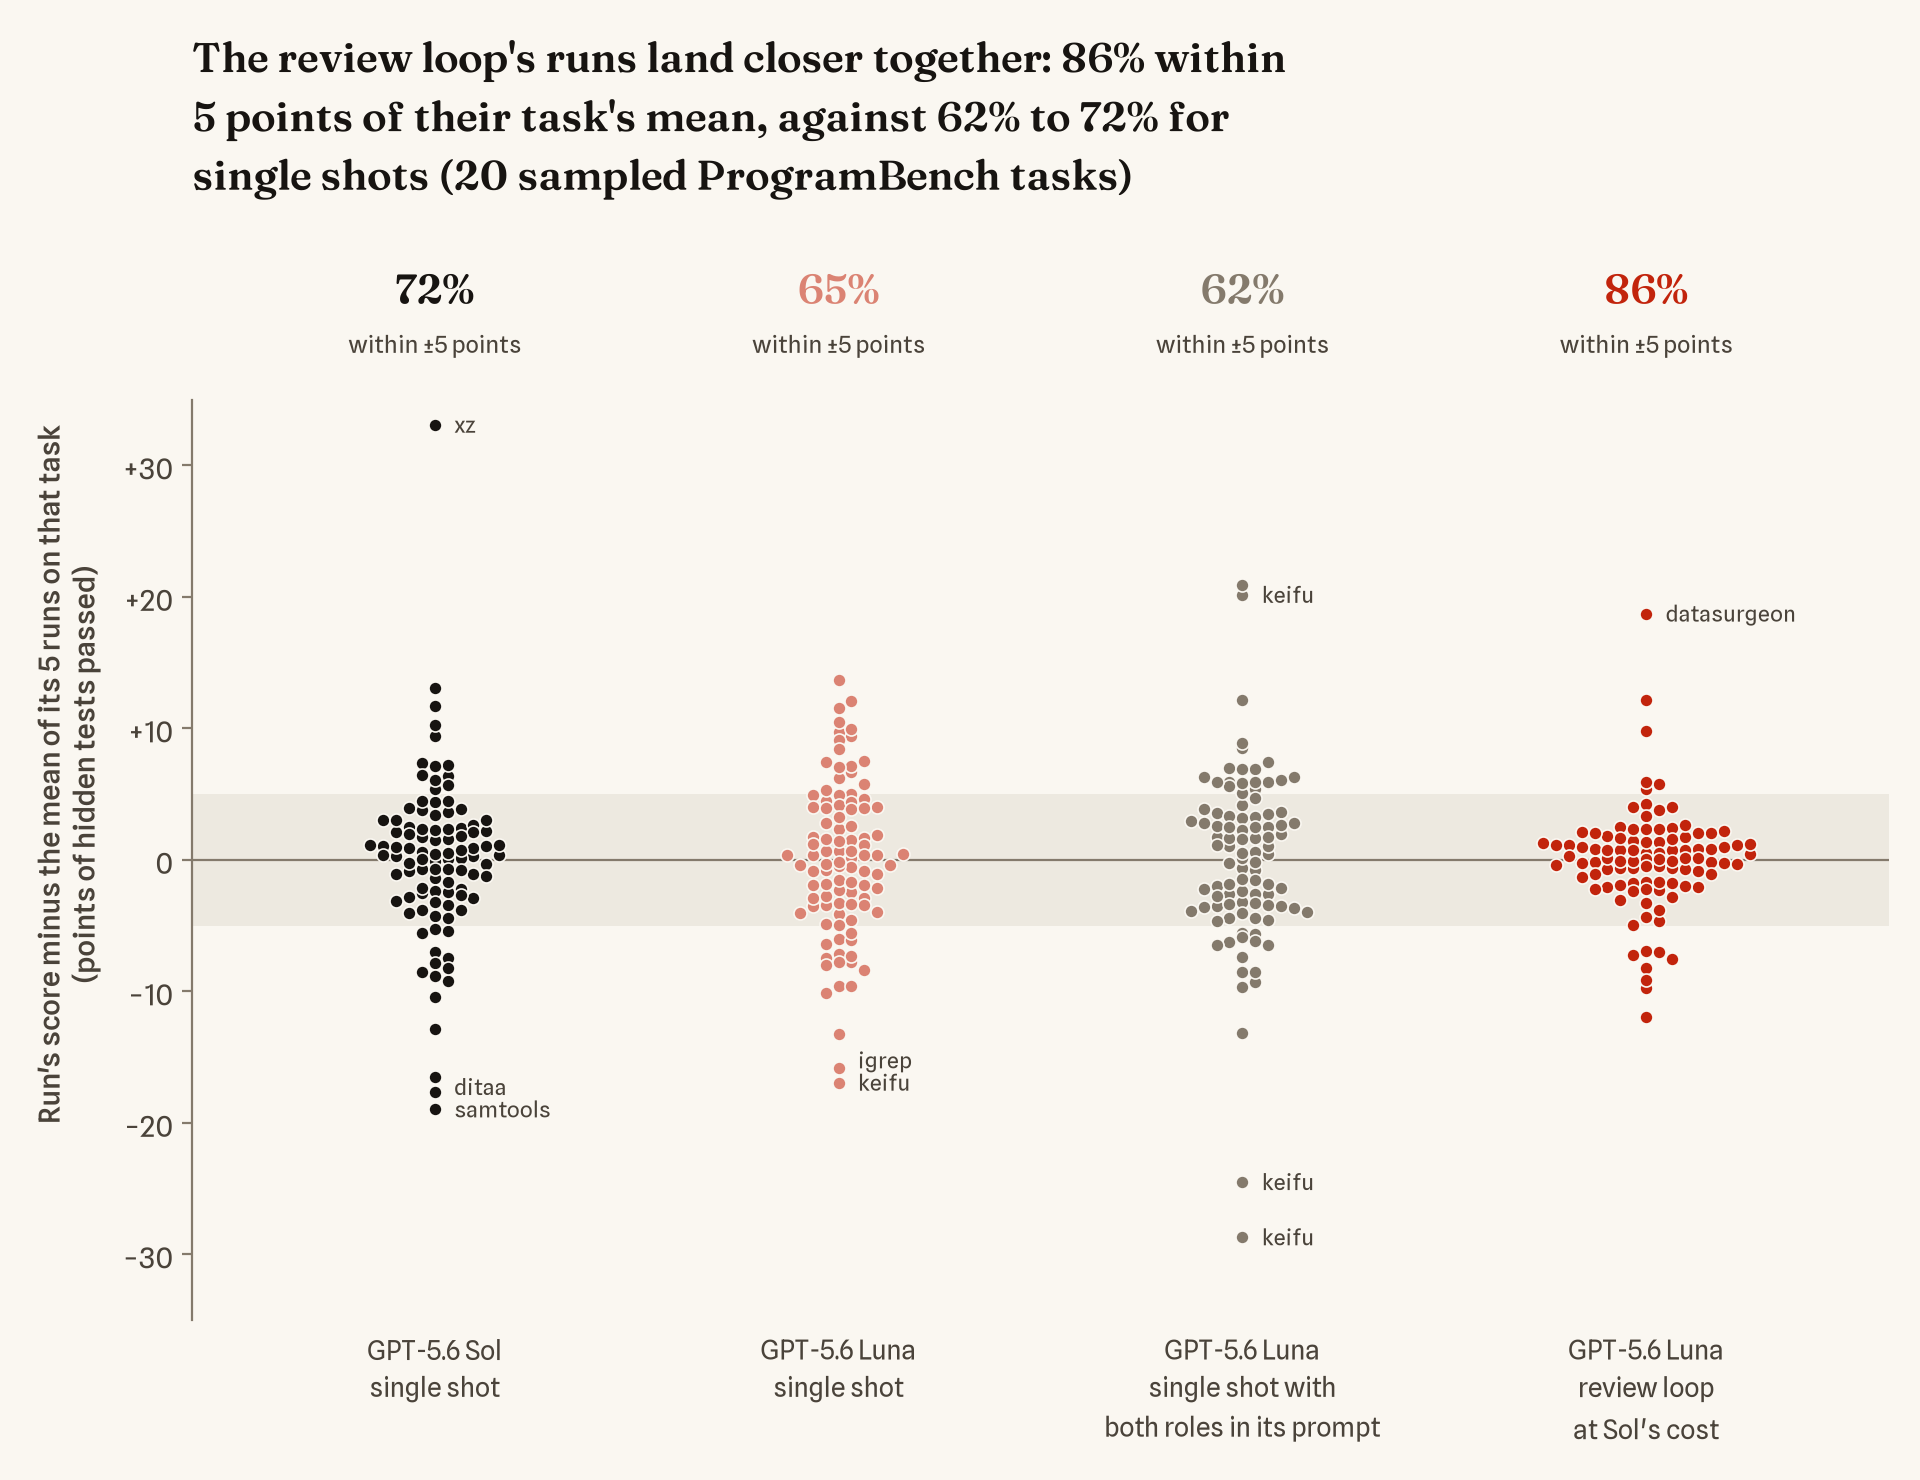
The difference from Sol was mostly in the outliers. Four of Sol's 100 runs ended more than 15 points from their task's mean. The loop had one such run, above the mean.7 Without those outliers, 85% of Sol's runs and 87% of the loop's were within five points of the mean. No loop run fell more than 15 points below its task's mean. Sol's single shot had three such runs, Luna's had two, and the role prompt had two.
Conclusion
A small model with a separate checker reached a larger model's score at a median 58% of its cost on these tasks. It also avoided the badly failed runs seen in every single-shot setup. Reaching that score took about six times as long as Sol's single shot. Asking one session to build and check didn't produce the same improvement, because all of those sessions stopped after one build.
This supports the idea behind zeroshot that a separate checker can find problems the builder misses and send them back for repair. We used two nodes and fixed prompts here. A graph can also include parallel builders, reviewers for tests, code and requirements, and verifiers with their own tools. Whether those task-specific workflows can reduce the cost further is something we still need to measure.
Limitations
- 20 tasks, not the whole benchmark. We chose five by hand. These were svgbob and ditaa from a shortlist of programs that are small by code size and rarely solved by published runs, and calcurse, revive and fasttext by a rule (at most 800 hidden tests over more than one test branch, Sol's published run between 15% and 80%, the best published run at least 5 points higher, one task per language not yet covered, and within each language the domain least like the two diagram renderers). The other 15 we drew at random, with a recorded seed and stratified by language, from 72 eligible ProgramBench tasks. Eligibility required Sol's published single-run score to be between 10% and 90%, the best published run to be at least 5 points higher, and at most 1,500 hidden tests spread over more than one test branch.
- One model family, one harness. Luna and Sol are two models in the GPT-5.6 line, driven by the Codex CLI.
- Five runs per arm. The figures show 95% bootstrap intervals over those five runs. Some intervals are wide.
Setup and what we changed
Code, experiment files, every per-task result and the figure scripts are on the benchmark/programbench branch of the zeroshot repository.
- Harness
- zeroshot 10.8.0 driving Codex CLI 0.155.0 inside the official ProgramBench task image, instead of mini-SWE-agent, the scaffold the benchmark ships with. The task statement is the upstream mini-SWE-agent prompt with only its scaffold mechanics removed (the persona line, the one-command protocol, the submit sentinel and the command examples). Our unit tests re-derive it byte for byte.
- The reference binary
- ProgramBench puts the reference at
./executable, which is also the build target. With the task unmodified, builders overwrote the reference, the checkers then had only a README that contradicts the binary in places and enforced it, and the loop gained nothing. So we moved the reference to a root-owned, execute-only path outside the workspace and pointed the task statement there. Every number in this post comes from that setup, both arms alike. The reference stays a black box that can be run but not read, and instrumenting it through the dynamic loader or ptrace disqualifies a run. - Documentation
- As shipped, except on svgbob, where we corrected three README statements that contradict the binary, for both arms.
- Network
- Tool commands have no route out, as under upstream's
--network none. Only Codex reaches the model API, through a per-attempt proxy that allows nothing else. Web search is off. - Limits
- Six hours per attempt, as upstream, with three hours per build and one per check. There is no step limit.
- Scoring
- ProgramBench's own evaluator on the task image, hidden tests pinned, identical workspaces scored once. Each task's smoke test re-scores a published submission and asks for agreement within 2 points. Four tasks failed that gate (crowbook, dust, samtools, tree-sitter) and stayed in the study, because the causes touch both arms the same way.8 We compare arms within this setup and treat leaderboard numbers as context.
- Audits
- We scan every run's shell commands. Instrumenting the reference, a tool command calling the model API or reaching the network through Codex's proxy, reading process environments or searching the web disqualifies a run. All 300 runs in these numbers passed. We also diff each check against the preceding snapshot to confirm the checker edited nothing.
Notes
- The median is over all 20 tasks, with the two tasks where the loop never reaches the target counted as the most expensive outcome. Over the 18 where it does reach the target, the median is 49%. For xz we checked the loop's final builds, all below Sol's mean, rather than every intermediate build. ↩
- Two of Sol's five ditaa runs scored near zero and count under the benchmark's rules. javac rejected one run's source because of a non-ASCII character. The other lost a test branch to the scorer's one-hour limit (ProgramBench runs each task's hidden tests in separate groups, its test branches, each under that limit). Without those two runs Sol's ditaa mean is 29%, still 18 points behind the loop, and the loop reaches it for 7% of Sol's cost partly because that mean is so low. ↩
- The loop's samtools win depends on a Sol run that lost its largest test branch to the scorer's one-hour limit. Without that run, Sol would lead there by a point. On xz, Sol's mean rests on one strong run among four weak ones. ↩
- One direnv loop run is left out of this comparison because the scorer counted one extra test on its first build. Another direnv run had finished two builds within the budget. ↩
- 91 of the 100 loop runs ran all 50 rounds. The other 9 stopped between rounds 23 and 44. ↩
- The labelled outliers in the figure are mostly the runs in notes 2 and 3. Sol's are the two ditaa runs and the samtools run, plus one unusually good xz run, and Luna's single shot has one each on igrep and keifu. The role-prompt sessions' are all on keifu, where three sessions landed at 68 to 77% and two near 30%. The loop's outlier is on datasurgeon, where three runs plateau near 53% and two reach 75 to 82%. ↩
- Sol's four outliers are the two broken ditaa runs, the stalled samtools run and the very strong xz run. The loop's outlier is a datasurgeon run 19 points above its task's mean. ↩
- On crowbook, the published run fails tests that pass here. On dust, the golden files (the expected outputs) bake in filesystem block sizes, and one test branch's pytest plugin won't load. On tree-sitter, 33 tests pass only here. On samtools, one test branch stalls past the evaluator's one-hour limit. ↩